Validated Inference flows
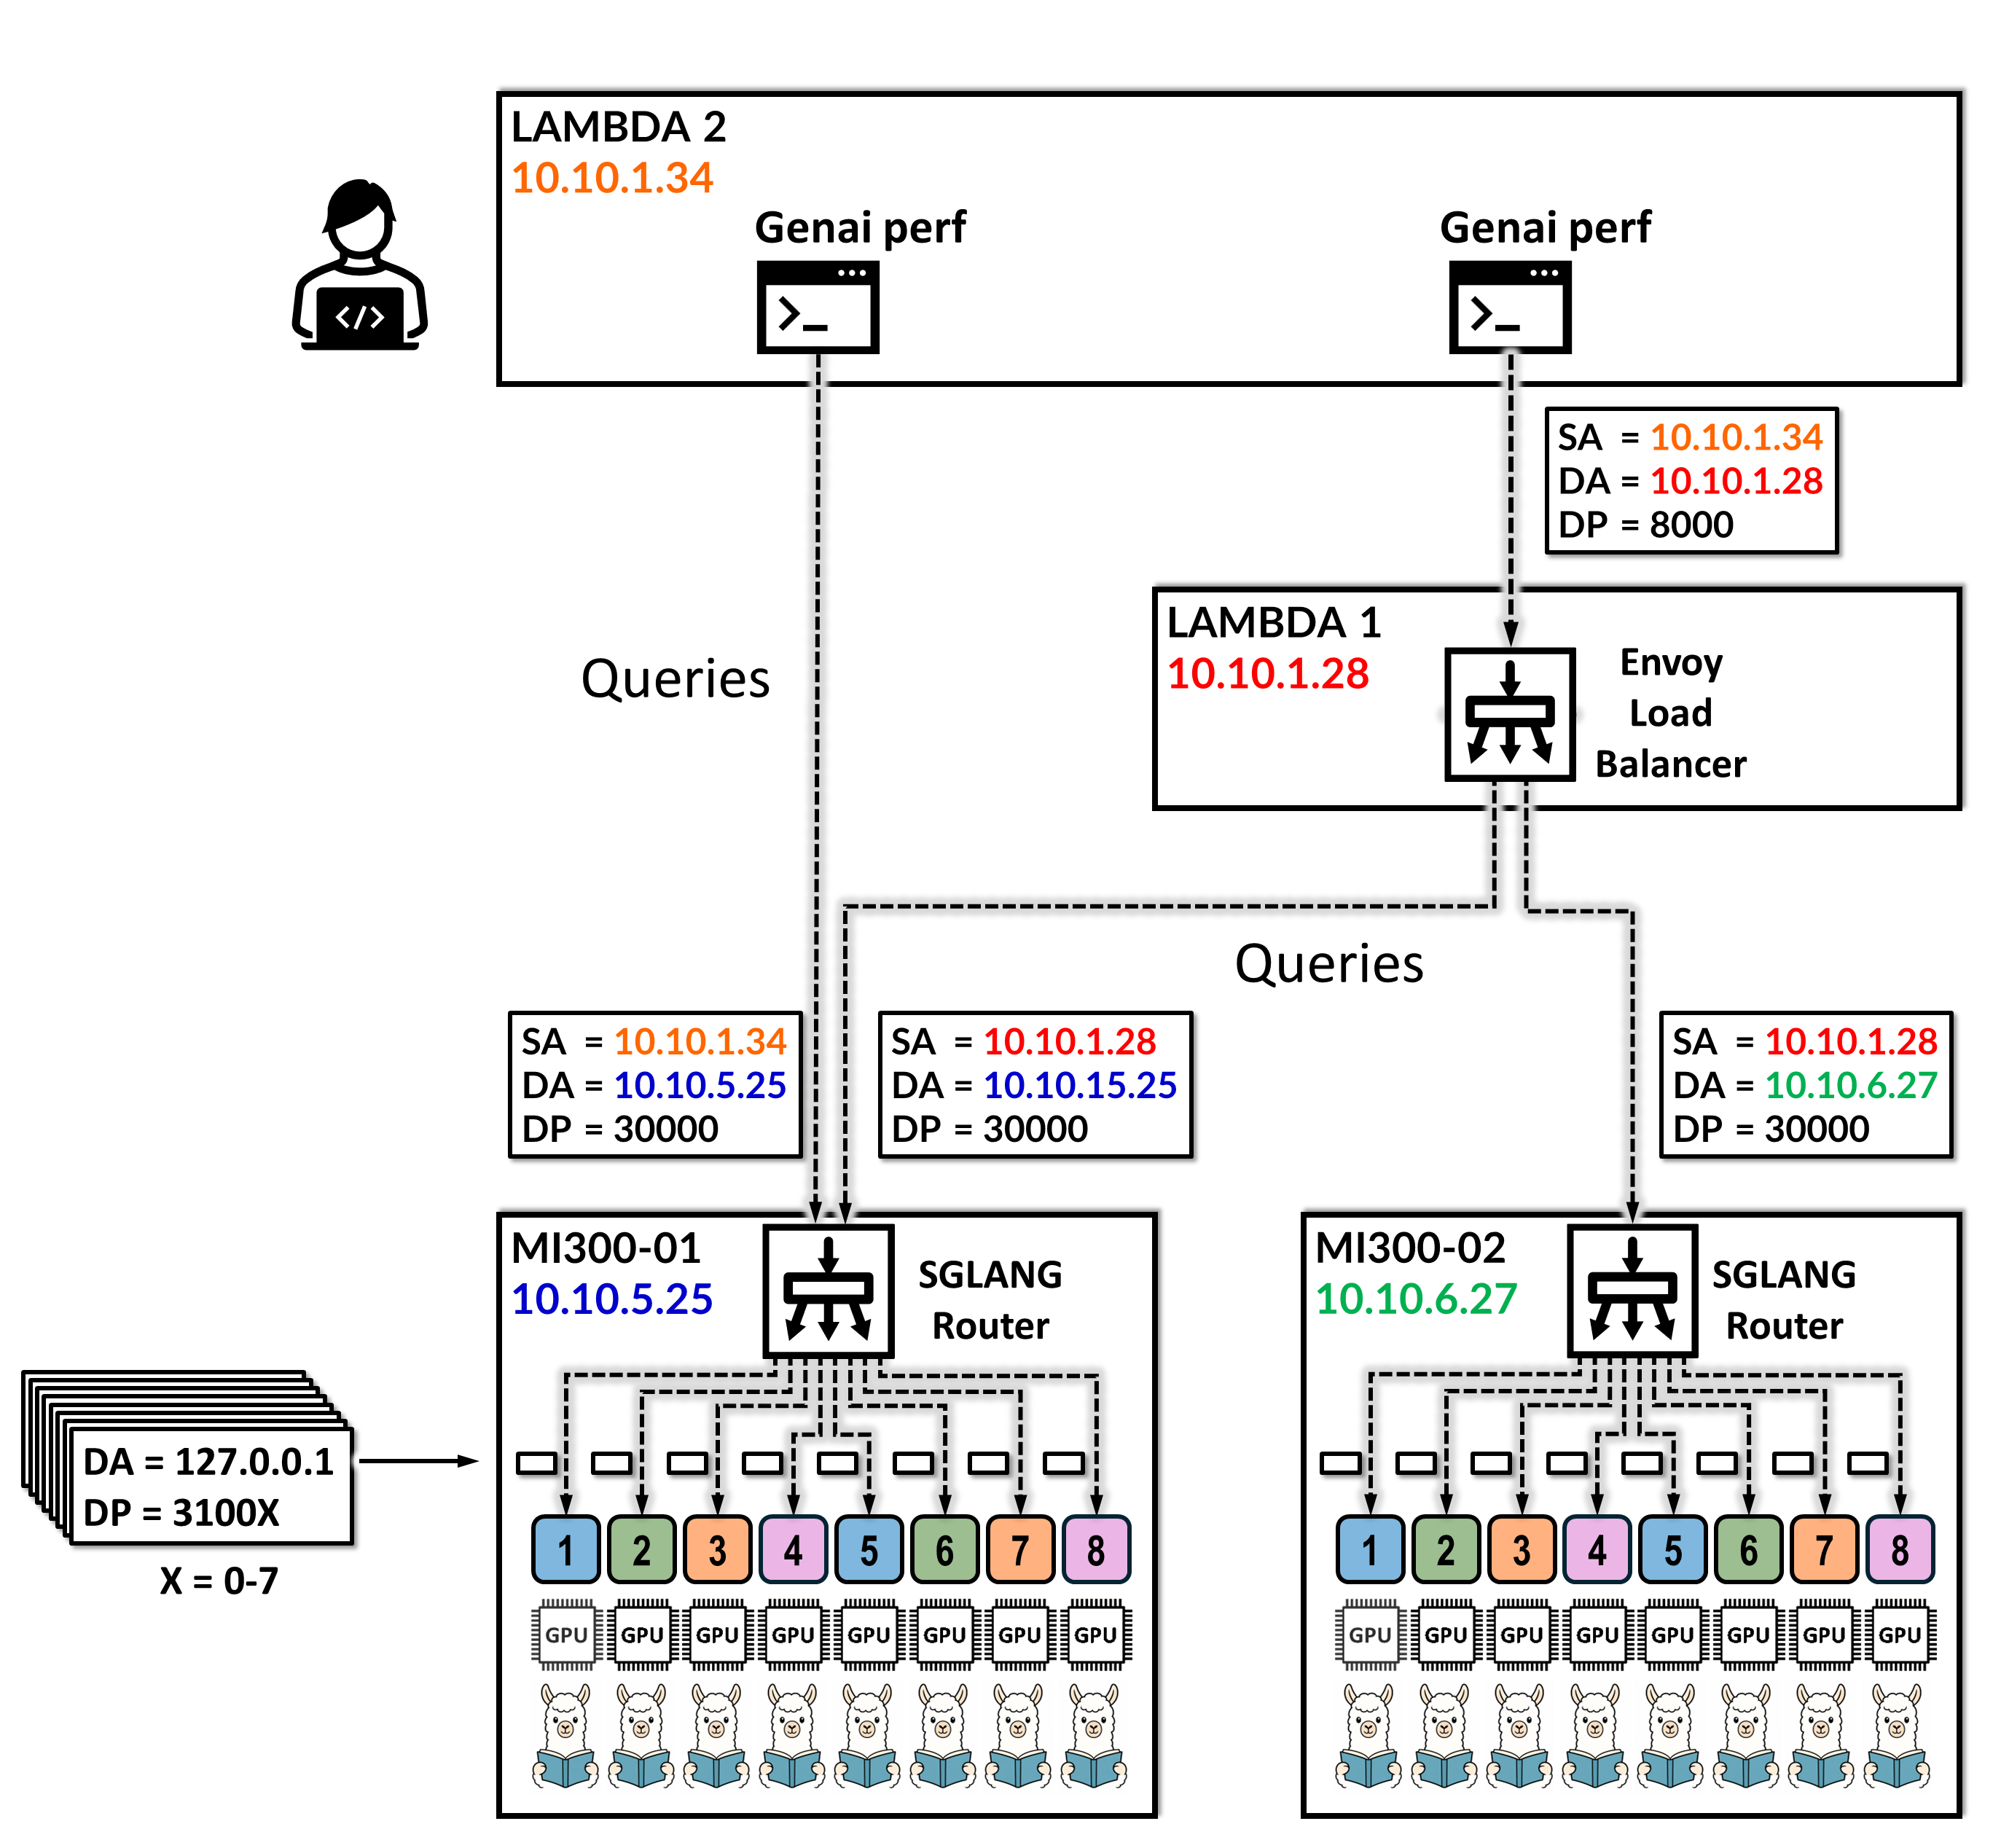
The inference traffic flows include two primary modes, as shown in Figure 4:
- Single-node inference
- Multi-node (Load balanced) inference
The following sections describe each in more detail.
Note: These workflows assume that each validated
model instance fits a single GPU. More complex serving models,
including distributed inference, multi-GPU model parallelism, may
be explored in future updates of this JVD.
Figure 4: GenAI-Perf, Envoy, and SGLang Inference Traffic Flow